
Hashing is everywhere in security, and for good reason. It’s how we verify data integrity, secure passwords, and much more. In this post, we’ll unpack what makes hashing so useful and see it in action.
Over the past two posts we’ve learnt how cryptography can be used to encrypt and decrypt data, and how symmetric and asymmetric algorithms divide that work between them. However, encryption is just one aspect of cryptography. When we first introduced cryptography we highlighted that it provides a mechanism to:
- Stop unauthorized parties from being able to access data.
- Verify data integrity, i.e. verify if information has been altered.
- Authenticate data, i.e. did X data originate from Y person/system?
So far we have discussed points 1 and 3, however, we haven’t touched on point 2. An introduction to cryptography would not be complete without discussing ✨ hashing ✨. This is the last foundational cryptographic concept we’ll cover in this series.
Data Integrity
The concept of integrity is to make sure something is complete, accurate, and consistent. In the physical world we rely on our senses (sight/touch/etc) to validate the integrity of things. For example, if you park your car, go shopping, and come back, you would most likely notice the integrity of your car is compromised if the window is broken or something is missing. This works because we measure the state of something now against a known state from the past.
The same principle applies to the digital world, to validate the integrity of data we need to be able to measure the current state of the data against the state of the data from the past. In practice, we could do this by keeping two copies of the data, the data now and the data from the past. However, that is incredibly inefficient, imagine having an identical second car to compare your current car against, especially in this economy 😂. To fill this gap we can use cryptography to provide a more efficient and effective solution.
Cryptographic Hashing
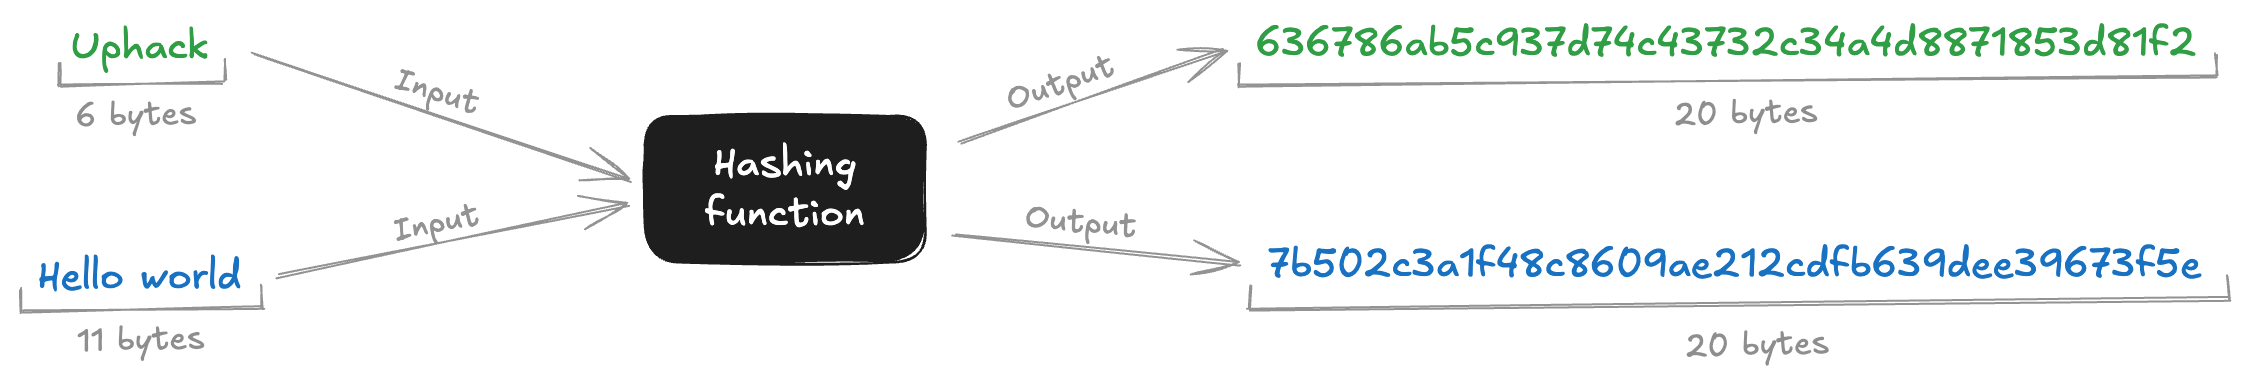
Cryptographic hashing, or just hashing, solves the data integrity problem by providing a mechanism to uniquely identify data. Hashing does this by converting data of any size into a unique fixed-size string of characters. Think of it like a fingerprint for data. Just like how each person has a unique set of fingerprints, each piece of data has a unique hash.
For example, let’s say you have the data uphack. A cryptographic hash function could transform that into a unique string of characters, such as:
7a11eb6898ff20bda5b518713221bbf17e410f819efd4db9a5de5bc025728432This unique string output from a hash function is referred to as a digest. If we change just one letter of our input to upback, you’ll notice almost none of the digest survives:
f1023507dafa081c378594832b01462b2f9b6b721543668ebf9f6692659a8f55Fifty-nine of those sixty-four characters changed, from a single letter of input. That property has a name, the avalanche effect, and it is what makes a digest usable as a fingerprint: there is no such thing as a small change. Both digests below are computed in your browser, so change either input and watch what survives.
Try it
Two inputs, one letter apart
Digests · 32 bytes each
In practice, we can use hashing to compare digests without having to store the data itself. For example, if we want to see if the input “uphack” matches “upback” we would simply hash both values, and then compare the hashes. If the hashes match, the data is the same, if the hashes don’t match, the data is different.
Hashing vs Encryption
You might be thinking, this sounds a lot like encryption? We’re putting some data in and getting back something that we can’t read. This is where it gets interesting. Unlike encryption, hashing is a one-way process. You can’t take a digest and “un-hash” it to get the original data. This means a hash does not provide any information about the original data. The only way you can get the original value from a digest is by guessing the input, recalculating the hash, and comparing it against the original digest.
Going back to the example from the previous section, the only way to get the value “uphack” from the digest “7a11eb6898ff20bda5b518713221bbf17e410f819efd4db9a5de5bc025728432” is to brute force it. Brute forcing in this context means you would have to try every possible input until you calculate a hash that matched your target digest.
Try it
Try to reverse it
A five-letter lowercase secret went in. Only its digest came out.
Target digest
e6f0a1fbb43c89196dcfcbef85908f19ab4c5f7cc4f4c452284697757683d7ef
Or let the machine guess
0 tried
You might have noticed that we didn’t also mention the use of keys here as a differentiating factor between encryption and hashing. Although most hashing functions do not use keys, some hashing functions like Hash-Based Message Authentication Codes (HMAC) do. Don’t worry about that for now, just remember that hashing is a one way process.
Hashing in Practice
Now that we know what hashing is, let’s discuss some of its real world applications to bring it to life. Hashing has an ever expanding number of use cases, for example:
- Let’s say you have anti-virus software on your computer. How does the anti-virus software know a file is malicious? Hashing of course! Anti-virus software providers maintain a list of digests for malicious files. When you perform a virus scan, the anti-virus software calculates the hash of the files in your system. If any of those file digests match the list of known bad hashes, the anti-virus flags it and most likely removes it.
- Let’s say you want to log into your phone, today this is usually done through a biometric (usually a fingerprint/face). How does it know your biometric matches? Hashing of course! When you unlock your phone, your phone generates a hash of the biometric data and compares that digest with the digest it has stored.
Crazy right? There are so many security critical operations that depend on hashing. However, hashing isn’t just for security, it has critical functional applications too. For example:
- In software development almost all programming languages have data structures that are based on hashing. Specifically, the HashMap and HashSet data structures. These data structures use hashing to store data in a set location in memory based on the value of the data. This has huge efficiency and performance benefits.
- Web browsers save web page assets locally after you visit a web page once to avoid having to download the same assets over and over again. How does the browser know if an asset has changed? Hashing of course! The browser compares the hash of the asset locally vs the asset on the remote server.
Hashing has a disproportionate impact on how we design, build, and secure modern systems. For example, in the phone example above, hashing means your phone never actually knows your biometric information. Therefore, if someone found a way to extract the biometric information, they would have a digest not your actual biometric data. We’ll see how that plays out differently when we look at authentication and authorization in web applications.
Security of Hashing Algorithms
We’ve seen that hashing has a wide variety of use cases, however, how do we measure the security of a hashing algorithm? There are two primary measurements:
- How long it takes to reverse a digest back to the original plaintext. A hashing algorithm is considered secure if the time taken to reverse a digest is equal to the time taken to brute force the digest.
- How unique is each plaintext to digest? A hashing algorithm is considered secure if each unique plaintext produces a unique digest (technically referred to as collision resistance).
Much like encryption algorithms, hashing algorithms come and go (rest in peace, Caesar cipher).
Most notably in recent memory, the Message Digest Method 5 (MD5) algorithm in 2013 was found to be vulnerable to collision attacks. Researchers found that it was possible to have two different inputs produce the same digest (known as a collision). This meant hashes generated using MD5 no longer provided complete assurance on the integrity of files.
Today the industry standard hashing algorithms are Secure Hash Algorithm 2 (SHA-2) based, specifically, the SHA-256/512 algorithms. The number at the end (256/512) specifies the size of the digest output. The larger the number, the larger the digest and the slower it is to compute. For example, the digest we looked at earlier for “uphack” was generated using SHA-256:
sha256("uphack") = 7a11eb6898ff20bda5b518713221bbf17e410f819efd4db9a5de5bc025728432Tip
Fun fact, you may be thinking “that isn’t 256 characters long”. Correct, it’s 64 characters long, 256 is the number of bits. Each character represents 4 bits, 64x4 = 256!
You might be thinking “cool, so everyone uses SHA-256/512 algorithms right?”. For security based decisions like the biometrics example from earlier, that is the recommendation yes. However, not all use cases have the same security requirements. For example, going back to the web browser example from earlier, why does a web browser need to use SHA-512 to check if it needs to download an updated asset? Sure SHA-512 is secure, but it is also slow. In this use case we care about speed, it would take more time to calculate the hashes than it would to just download the assets 😂. Therefore a decent and fast answer is better than a perfect and slow answer here. As a result, you’ll often still see modern applications using MD5 for non-security related decisions.
Note, there are additional security considerations like randomness, preimage and second preimage resistance but don’t worry about that for now. Just remember that the security of the algorithm itself, and the use case is important.
Conclusion
Hashing provides a mechanism to represent data of any size as a unique fixed-size string of characters known as a digest. We can use these digests to verify the integrity of data by calculating the hash of the data now, and comparing it against a known good digest. This allows us to efficiently and effectively validate the integrity of data without having to store the data itself.
Hashing is foundational to countless functional and security use cases. From virus scanning to authentication to enabling efficient data structures, hashing is everywhere. These use cases play a critical role in which algorithms we apply. Industry standard algorithms like SHA-256/512 are the latest and greatest for security, however, they are slow. Insecure but fast algorithms like MD5 still have impactful functional use cases for non-security based decisions.
This post only touched the surface of hashing. That was deliberate, because so much of what comes later is built on top of it: authenticated hashes, salting, and password-specific algorithms like PBKDF2, bcrypt and Argon2. Those belong with the problems they solve, so they’ll turn up when we get to storing credentials rather than here.
That closes the cryptography foundations for this series. If you haven’t read it yet, fundamental security principles is a good next stop: it covers how developers release software and how to structure your thinking to improve security at scale.